AI Development
AI App Development: Where AI Actually Adds Value to a Product
Practical guide to building AI-powered apps and features. LLM prompt architecture, RAG systems, latency optimization, and avoiding gimmick AI.
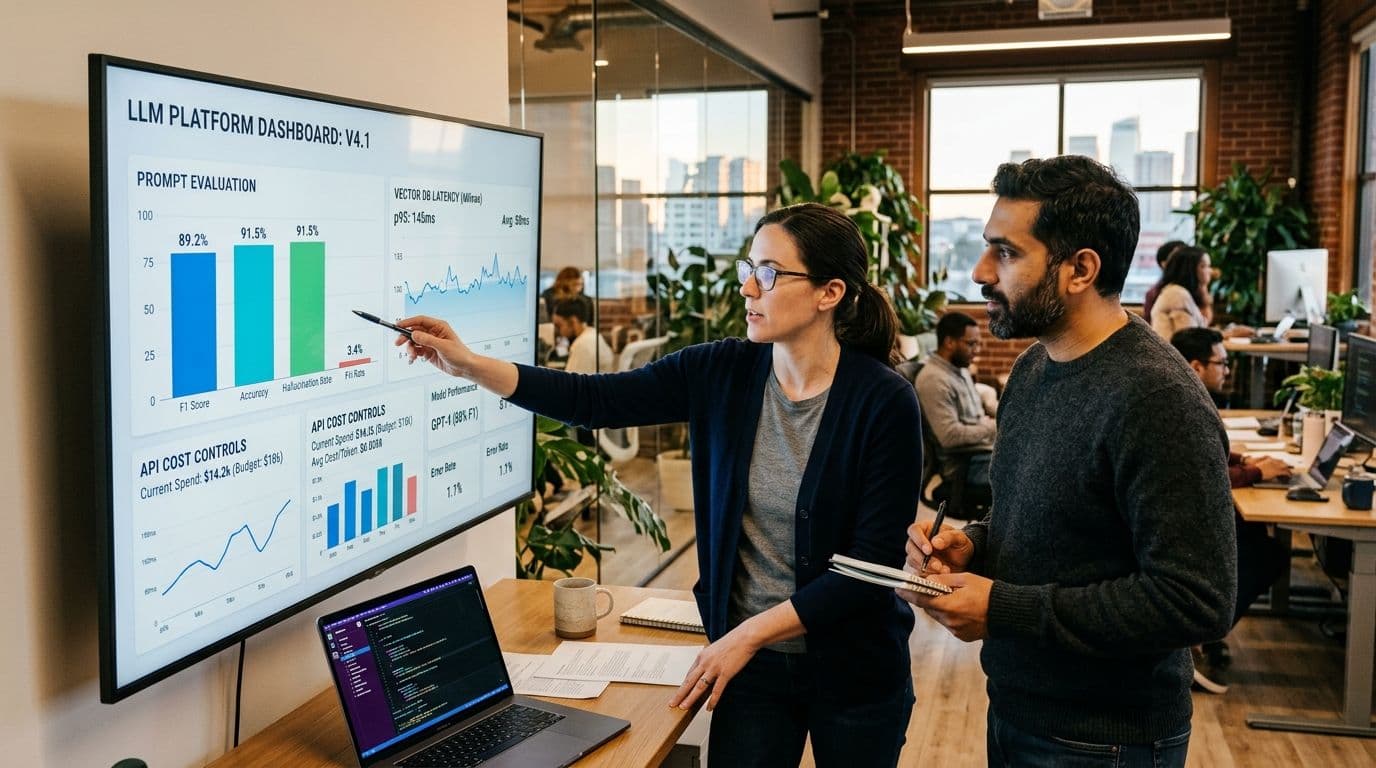
In 2026, simply plugging a generic ChatGPT wrapper into a product is no longer enough to impress users or investors. Users have high expectations for speed, accuracy, and reliability. Building a defensible, high-utility AI product requires software engineering discipline: structured data outputs, Retrieval-Augmented Generation (RAG), prompt caching, and cost guardrails.
Discover how Frontail builds reliable, production-ready AI products in our [AI development services](/services/ai-development).
The 4 Highest-Value AI Product Patterns for Startups
- **1. Document & Unstructured Data Intelligence (RAG):** Allowing users to query private PDF contracts, technical documentation, or internal databases with cited sources and zero hallucinated facts.
- **2. Automated Workflow Extraction & Triage:** Using lightweight models (Claude 3.5 Sonnet / GPT-4o-mini) to extract structured JSON data from messy emails, support tickets, and invoices.
- **3. Contextual In-App Assistants:** Integrated copilot sidebars that can execute real database actions (e.g. 'schedule meeting', 'refund transaction') with human confirmation safeguards.
- **4. Intelligent Data Summarization & Reporting:** Generating automated executive summaries, weekly performance digest emails, and anomaly alerts across large customer datasets.
The 4 Technical Pillars of Production-Grade AI
- **Structured Outputs via Schema Validation:** Enforcing strict Pydantic / Zod JSON schemas on all model outputs to prevent frontend rendering crashes.
- **Model Tiering & Cost Controls:** Routing simple classification tasks to fast, ultra-cheap models (GPT-4o-mini) and reserving reasoning models (o1/Claude Opus) for complex multi-step tasks.
- **Vector Embeddings & Semantic Search:** Storing document embeddings in pgvector (PostgreSQL) or Pinecone for sub-100ms context retrieval.
- **Asynchronous Background Workers:** Never running heavy LLM inference synchronously inside user HTTP request threads. Use BullMQ/Redis worker queues with streaming UI updates.
Adding AI to Existing Web and SaaS Platforms
If you already run a live application and want to introduce automated AI workflows, read our technical walkthrough on [how to add AI to an existing SaaS product](/blog/add-ai-to-saas).
Ready to build a reliable, high-retention AI application? [Book an AI scoping call with Frontail](/contact) today.
Related Posts
View all
MVP Development
How We Plan a Software Product From Idea to Launch
A transparent look at the modern software engineering lifecycle: discovery, technical architecture, agile sprint delivery, QA testing, and launch.
Read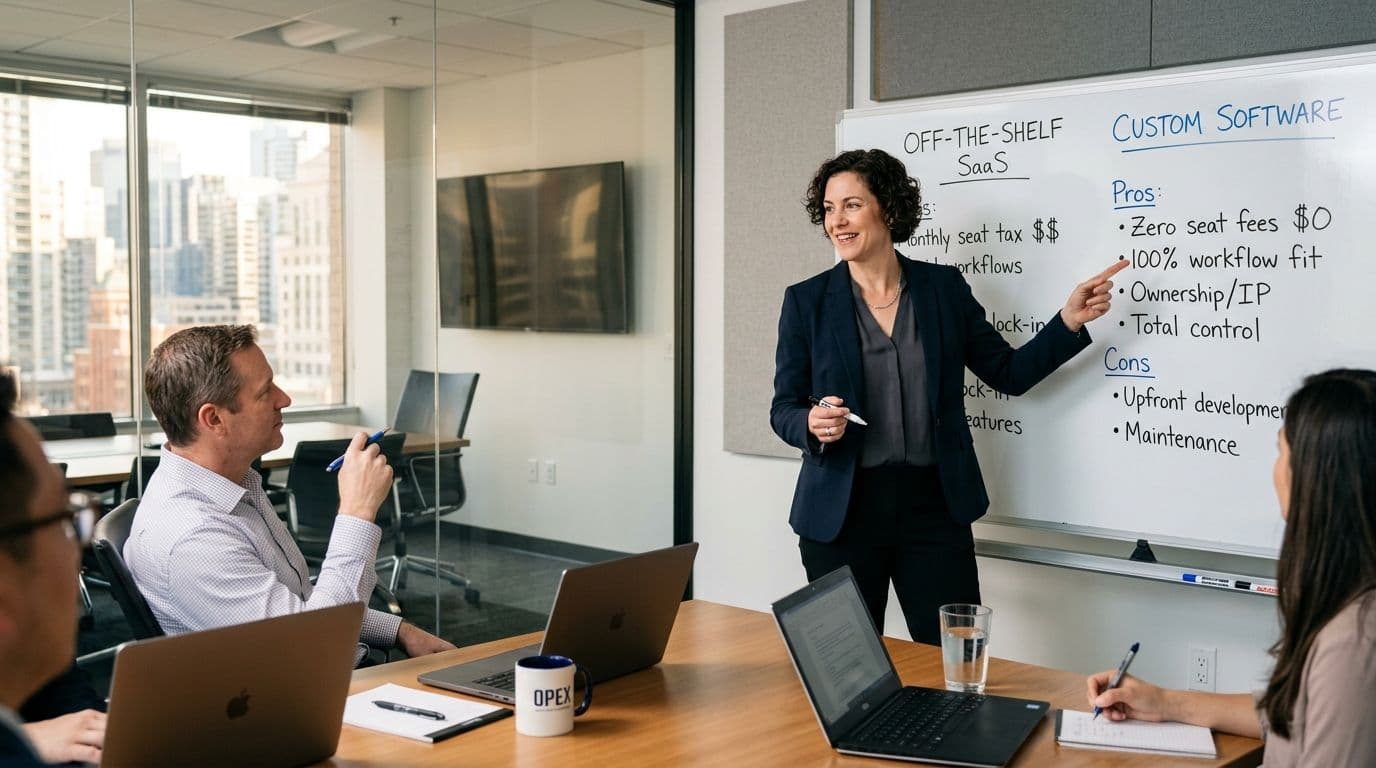
Custom Software Development
Custom Software vs Off-the-Shelf Software: Which Should Your Business Choose?
Compare custom software development vs off-the-shelf SaaS. Total cost of ownership, operational fit, scalability, and decision framework.
Read